

Statistics · Guide · · 5 min read
Stratified modeling for imbalanced data in R
How logistic regression responds to a rare outcome, what the usual fixes are, and how stratified modeling with the medley package works.

When one category of a binary outcome is rare, for example when only a few percent of participants experience an event, logistic regression behaves differently than with balanced data. In this guide I explain the stratified modeling approach that Jason Bryer described alongside his R package medley. I also show where it fits among better-known solutions.
Why imbalance is a problem
Models with an imbalanced outcome tend to favour the majority class. King and Zeng (2001) showed that logistic regression can sharply underestimate the probability of rare events.
Bryer illustrates this with US PISA data. The dataset has 5,233 students, of whom 345 (about 6.6%) attend private schools. As the ratio of public to private schools in the model grows from 1:1 to roughly 14:1, the range of fitted probabilities narrows and shrinks towards the majority group.
Common fixes and their drawbacks
- Downsampling the majority class: you discard part of your data.
- Upsampling the minority class: repeating observations artificially inflates the sample size, so standard errors are too small.
- SMOTE (Chawla et al., 2002): creates synthetic minority examples. Combined with downsampling, it performed better in ROC space than downsampling alone, but it is aimed mainly at classification.
- Rare-events corrections (King and Zeng): adjust the estimates and allow more efficient designs, such as sampling all events and only a small fraction of non-events.
How stratified modeling works
- Separate the minority and majority classes.
- Randomly split the majority class into non-overlapping subsets. The subset size follows the chosen ratio (1:1 by default), which gives 14 models for the PISA data.
- Each model uses the whole minority class plus one majority subset. Every majority observation enters exactly one model.
- Pool the results with Rubin’s rules, known from multiple imputation (the
mitools::MIcombinefunction). You get one coefficient and one standard error per predictor, with no artificial shrinkage of the error.
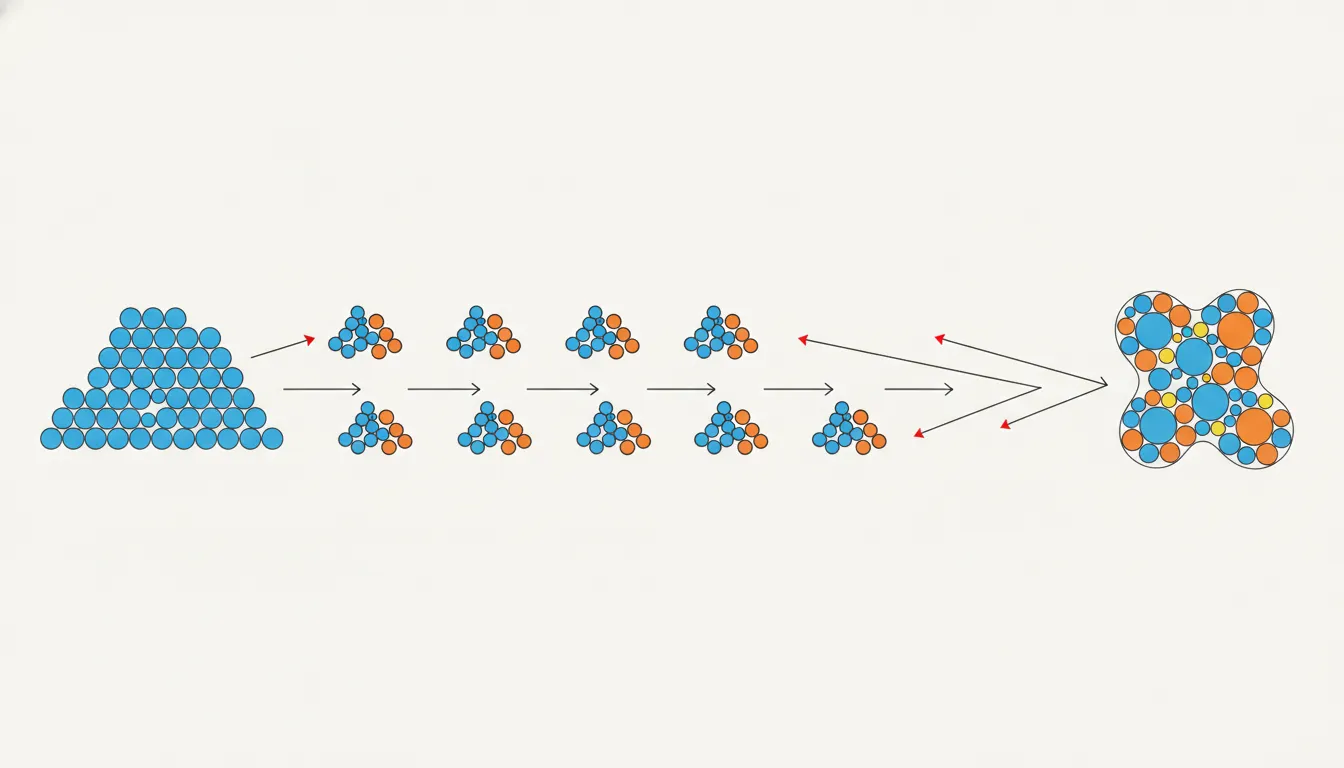 The majority class is split across models, the minority class enters every model, and the results are pooled with Rubin’s rules. · Illustration: AI-generated
Example in R
results <- medley::stratified_glm(
  formula = Private ~ .,
  data = pisa,
  ratio = 1
)
summary(results)   # coefficients, SE, p
plot(results)      # distribution of fitted probabilities
predict(results, newdata = pisa)
The function passes arguments on to glm(), but avoid those that refer to individual observations (weights, subset), because the models are fitted on subsets. It works only with two outcome classes, and family defaults to binomial(link = 'logit'). The individual models are stored in the model element and their fitted values in fitted.
What you gain and what you don’t
Fitted probabilities from the stratified model span the full range from 0 to 1 and are easier to interpret. With a 3:1 ratio the effect is weaker.
For prediction there is almost no difference. On a validation set (80/20 split), the AUC was 0.747 for the full model and 0.745 for the stratified one. What changes is the threshold: the point where sensitivity and specificity intersect is 0.059 for the full model and 0.509 for the stratified model, close to the familiar 0.5 cut-off. The author stresses that the method is neither better nor worse for prediction. You get a similar result by keeping the full model and adjusting the threshold.
When it makes sense
The approach grew out of propensity score analysis, where the propensity score is the conditional probability of belonging to the treatment group (Rosenbaum and Rubin, 1983). With logistic regression, propensity scores are simply the model’s fitted values. If they are squeezed towards one group, comparing the groups becomes harder. This is where stratified modeling can help.
Ukratko
- A rare outcome shrinks logistic regression’s fitted probabilities towards the majority class.
- The stratified approach uses all the data: the minority class goes into every model, while the majority class is split across models.
- Models are pooled with Rubin’s rules, so standard errors are not artificially reduced.
- For pure prediction, adjusting the threshold is enough. The main benefit is in interpreting probabilities and propensity scores.
Cover: AI-generated
Sources
- R-bloggers — Stratified Modeling for Imbalanced Data, 2026-11-03
- medley (Jason Bryer) – dokumentacija R paketa — Stratified Modeling for Imbalanced Data
- Gary King, Harvard University (Political Analysis) — Logistic Regression in Rare Events Data
- Journal of Artificial Intelligence Research (JAIR) — SMOTE: Synthetic Minority Over-sampling Technique


